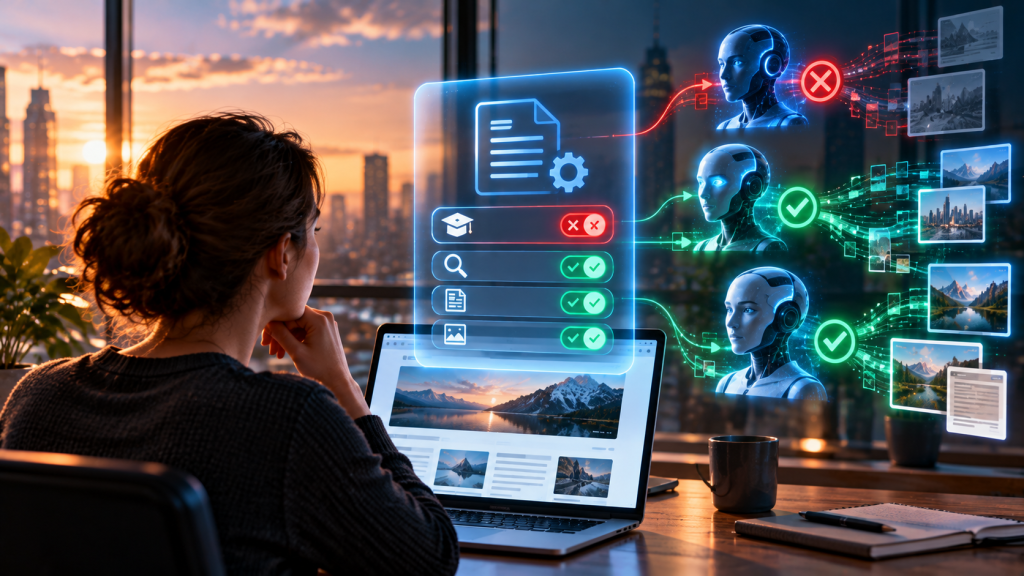
OpenAI has announced plans to support a shared system that will make it easier for website owners to express whether they want their content used to train generative AI models.
The announcement, published on October 30, 2026, focuses on a common signal in the robots.txt file, a familiar tool used by website administrators to communicate instructions to automated web crawlers.
Instead of requiring publishers to maintain separate AI training preferences for every participating company, the proposed approach would allow them to communicate a broader preference through a shared mechanism.
The important distinction is that OpenAI has announced its intention to implement the system in the coming months. It has not announced that the new shared control is already active.
For website owners, independent publishers, and WordPress users, the development could eventually simplify an increasingly complicated part of managing online content. OpenAI
What Are OpenAI’s New AI Training Controls?
The proposed system is designed to help websites communicate their preferences about the use of published content for training foundational generative AI models.
Currently, website operators may need to manage different crawler instructions for different AI providers.
This can involve identifying specific automated crawlers and maintaining separate rules depending on how each company accesses and uses website content.
OpenAI’s new commitment supports a shared signal that participating AI companies can recognize.
In practical terms, the goal is to reduce the need for website administrators to configure similar preferences repeatedly for different providers.
However, the system is voluntary. Its effectiveness will depend on participating AI providers implementing and respecting the shared instructions.
How Will the Shared robots.txt Signal Work?
A robots.txt file is typically located at the root of a website.
For example, a website might have a file at:
https://example.com/robots.txt
The file allows website administrators to communicate crawling preferences to automated systems.
Under the proposed shared approach, website operators will be able to express certain AI training preferences through a common policy signal.
The central idea is straightforward:
- A website owner publishes an AI training preference in
robots.txt. - Participating AI providers recognize the shared signal.
- Those providers apply the preference according to their implementations and applicable policies.
This could make managing AI training preferences simpler for publishers who work with multiple AI companies.
Importantly, a robots.txt instruction is not a technical barrier that physically prevents content from being downloaded. It communicates a preference that cooperating crawlers are expected to respect.
The announcement also does not establish that the shared signal can retroactively remove content from datasets already collected.
OpenAI Says Existing Crawler Controls Will Remain Available
One of the most important details is that OpenAI does not intend to replace its existing crawler controls.
Website owners who already use OpenAI-specific instructions in their robots.txt files will continue to have access to those controls.
The shared signal is intended to complement existing mechanisms rather than eliminate them.
This distinction matters because website owners may have different goals for different types of automated access.
For example, a publisher might want its articles discoverable through AI-powered search experiences while preferring not to have the same content used for training future foundation models.
These activities should not automatically be treated as identical.
OpenAI has said it will provide further implementation details as the shared system moves closer to deployment.
Until then, website administrators should avoid assuming that adding an unverified new directive will immediately change how OpenAI uses their content. OpenAI
Google Also Announces Support for Shared AI Training Preferences
OpenAI is not the only major AI company supporting the initiative.
On October 30, 2026, Google also announced plans to support a shared AI training control based on work by the Internet Engineering Task Force’s AI Preferences working group.
Google explained that the proposed system would allow publishers to communicate broad AI training preferences through a shared policy token.
The company also outlined how the future control would interact with Google-Extended, its existing mechanism for expressing preferences about certain AI uses.
Google’s announcement is significant because it suggests the proposal could develop into a more widely recognized approach rather than remaining specific to one AI provider.
However, the companies have not announced identical deployment schedules, and support for a shared signal should not be confused with an already completed industry-wide rollout. Google for Developers
Why This Matters for WordPress Website Owners
WordPress powers websites ranging from personal blogs to professional publications and online businesses.
Many of these websites publish original articles, tutorials, reviews, research, and other materials that may be accessible to automated crawlers.
For smaller publishers, managing individual AI crawler rules can be time-consuming.
A shared AI training preference could eventually provide three practical advantages.
1. Simpler management of AI training preferences
Instead of maintaining multiple similar instructions for participating providers, publishers may be able to communicate a common preference more efficiently.
This could be particularly useful for websites without dedicated technical teams.
2. More consistent communication with AI companies
A common signal could reduce confusion caused by different crawler names and provider-specific configurations.
However, consistency will depend on how individual companies interpret and implement the specification.
3. Greater clarity about content usage
The proposal could help distinguish website owners’ preferences about AI training from other activities, such as ordinary search indexing.
This distinction is increasingly important as AI-generated answers, traditional search results, and automated content collection become more closely connected.
Will Blocking AI Training Hurt Google Search Rankings?
This is an important question for publishers who depend on organic search traffic.
OpenAI’s announcement does not establish that using the proposed AI training control will directly affect Google Search rankings.
Google has described its planned implementation in relation to Google-Extended and existing publisher controls.
Website owners should distinguish between restricting ordinary search crawling and communicating preferences about AI model training.
These are not necessarily the same operation.
A poorly configured robots.txt file can affect search crawling if it blocks important search-engine crawlers. That is a separate technical risk from the purpose of the proposed shared AI training signal.
For this reason, publishers should review the exact documentation before modifying their websites.
What Should Website Owners Do Right Now?
The new shared control is still moving toward implementation, so there is no need to rush into unverified configuration changes.
Website administrators can take several sensible steps while waiting for further details.
Review existing robots.txt settings. Check whether your website already contains instructions for AI-related crawlers or search engines.
Decide how you want your content used. Consider whether your priority is discoverability, limiting AI training use, or maintaining different preferences for different activities.
Keep existing controls in place. OpenAI has explicitly said its current crawler controls will continue to apply.
Follow official implementation announcements. Wait for confirmed syntax, compatibility details, and deployment information before adopting the new shared signal.
Test changes carefully. Any future modifications should be checked to ensure they do not unintentionally restrict important website crawling.
For WordPress users, the practical approach is to treat this announcement as an upcoming policy and technical development rather than an immediately available setting.
What Does This Mean for ChatGPT?
The announcement concerns the training of foundational generative AI models, not a newly released feature inside the ChatGPT interface.
OpenAI develops the models behind ChatGPT using multiple sources of information, including publicly available internet content, licensed or partnered information, and material provided through other channels.
The shared signal is intended to give website owners a simpler way to express preferences about one aspect of that process: the use of website content for foundational AI training.
It does not mean that ChatGPT will immediately stop referring to websites, that all AI search activity will cease, or that existing model knowledge will automatically be removed.
Readers interested in how ChatGPT compares with another major AI assistant can explore our ChatGPT vs Claude comparison.
When Will the New AI Training Controls Become Available?
OpenAI says it aims to implement the shared signal in the coming months.
The company has not provided a specific launch date in its October 30 announcement.
The initiative builds on work associated with the Internet Engineering Task Force’s AI Preferences working group.
Because the technical and standards discussions are ongoing, implementation details may evolve.
Publishers should therefore rely on official documentation rather than assuming that every proposed configuration is already supported.
Final Thoughts
OpenAI’s decision to support shared AI training preferences could be a meaningful development for website owners and independent publishers.
By reducing the need to manage separate rules for multiple participating AI providers, the initiative aims to make it easier to communicate how website content should be used for AI training.
Google’s parallel announcement adds momentum to the effort.
However, the shared control is not yet fully implemented across the industry, and its practical impact will depend on provider adoption and compliance.
For now, the most sensible approach is to understand the proposal, review existing crawler settings, and wait for confirmed implementation guidance before making changes.
Original Sources
Primary source: OpenAI — Making It Easier for Websites to Express AI Training Preferences. Published October 30, 2026.
Additional primary source: Google Search Central